The Pilot Project Myth: Small Does Not Mean Proven
A policy pilot can reveal what works locally, but careful questions about participants, delivery and scale help separate useful evidence from overreach.
A city runs a small evening bus pilot, and riders like the service. At the next budget meeting, someone says the trial proves the city should expand it everywhere. That leap is the pilot project myth: a limited trial can produce useful evidence without proving that a policy will work at a larger scale.
The right question is not simply whether a pilot succeeded. It is what the trial actually tested, what changed, and what remains unknown. When a pilot is treated as a miniature version of full implementation, its limits can disappear from the debate. Troubleshooting those limits means matching each claim to the evidence the trial could reasonably produce.
What did the pilot actually establish?
Start by describing the finding narrowly. A pilot might show that a particular service can be delivered to a particular group, in a particular place, under particular conditions. That can be valuable. It does not automatically establish that the same approach will reach other groups, fit different institutions or produce the same results at scale.
Separate three kinds of claims:
- Feasibility: Could staff deliver the service, and could intended participants use it?
- Outcomes: Did participants experience the change the policy aimed to produce?
- Scale: Could the approach retain those outcomes across more locations, participants or delivery teams?
A trial may offer a clear answer on feasibility and only an early indication about outcomes. Scale may not have been tested at all. Say you are reviewing a pilot that offered evening bus service on one route. If buses ran and riders used them, that supports the claim that this route could operate the service. It does not, by itself, answer whether other routes have enough demand, whether staffing can be sustained across the network or whether the service improves access for people who were not part of the trial.
Why might a successful pilot fail to travel?
A pilot often works inside a supportive setting that is difficult to reproduce. A local champion may solve problems quickly, a partner organization may contribute extra staff time, or managers may focus unusual attention on a new project. Expansion can replace those favorable conditions with ordinary workloads, different leadership and more complicated coordination.
What goes wrong: The pilot’s success is treated as evidence that the operating model is ready for routine use.
What usually causes it: The report describes the service people received but says little about the extra effort that made delivery possible.
What to try: Ask for a plain account of the work behind the results. Who handled referrals? Who answered participant questions? Which partner supplied space, translation or follow-up? Which tasks depended on an especially engaged manager? These details help distinguish a repeatable service from a service held together by temporary effort.
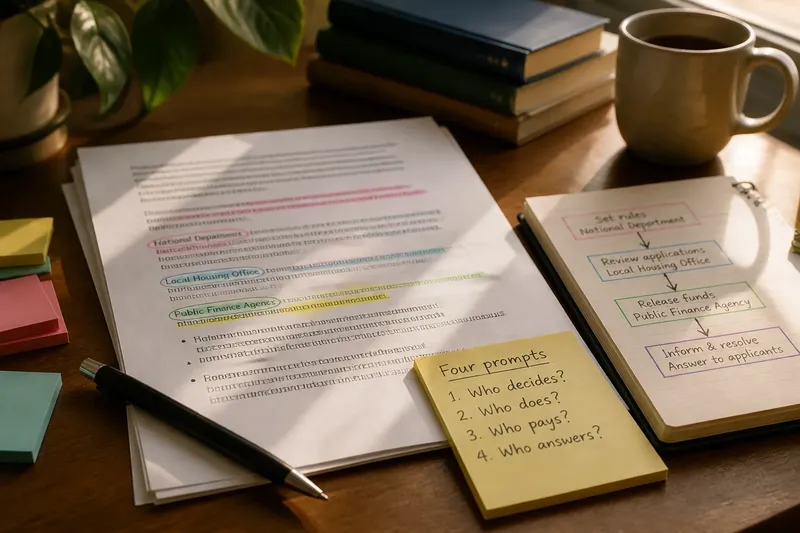
Look for a delivery plan that assigns ordinary responsibilities to named roles or organizations. If key tasks have no owner, the pilot has exposed a design gap rather than settled the case for expansion.
Who took part, and who did not?
A small group can be informative without representing everyone affected by a policy. Participants may hear about a program through a trusted organization, have time to complete an application, or live close to the service. People facing language barriers, unstable schedules or limited transportation may be less likely to enroll. Their absence can make a pilot appear easier to use than a broader service would be.
What goes wrong: Strong results among participants are presented as a result for the wider population.
What usually causes it: The evaluation counts people who joined but does not clearly describe the people who were eligible, reached, declined or could not take part.
What to try: Ask how participants were invited and how many eligible people did not enter the program, without assuming that a single count resolves the issue. Review enrollment rules, language access, location and schedule. Compare the pilot group’s circumstances with those of the intended population, then ask which differences might affect access or results.
If the pilot reached only a narrow group, that is not necessarily a reason to discard it. It is a reason to state the scope of the finding and consider a follow-on trial designed to reach people missing from the first one.
Did the trial show what caused the change?
Participants may report improvement during a pilot, but timing alone does not establish that the policy caused it. Other changes could have occurred at the same time: a partner may have introduced a separate service, local conditions may have shifted, or participants may have sought help elsewhere. A useful evaluation considers plausible explanations rather than treating every favorable change as the pilot’s effect.
What goes wrong: A before-and-after comparison is described as proof that the policy produced the difference.
What usually causes it: The evaluation records outcomes but has no credible way to distinguish the policy’s contribution from other influences.
What to try: Ask what comparison the evaluators used, if any, and what assumptions it depends on. Read the outcome measures closely: a measure should connect to the policy’s stated goal, not merely capture an easy-to-count activity. If the design cannot identify cause, the report can still describe participation, delivery problems and changes observed, while using more careful language about impact.
Do not dismiss descriptive evidence. Knowing that applicants could not complete a form, for example, can point to a practical design problem. Just keep an operational finding separate from a claim that the policy caused a broader social outcome.
Were the results built on extra support?
Pilots frequently receive temporary resources: dedicated coordinators, flexible funds, close oversight or help from an outside partner. Those supports can be appropriate for learning. But a policy that depends on them may not perform the same way inside a regular agency budget and workload.
What goes wrong: Decision-makers compare the pilot’s results with its visible costs while overlooking the less visible resources used to deliver it.
What usually causes it: Staff time, shared facilities and partner contributions are recorded informally or left out of the account.
What to try: Ask for a delivery map that lists the people, organizations and resources involved, including contributions that were temporary or in kind. Then ask what would need to change for those tasks to continue under ordinary operating arrangements. The purpose is not to demand a perfect cost model from an early trial; it is to avoid calling an arrangement sustainable before its dependencies are visible.
For the bus pilot, that might mean clarifying whether the trial used a temporary coordinator to resolve scheduling issues and whether the transit agency has a routine role for that work. The observable question is whether staff can assign and complete those tasks through the proposed operating arrangement.
How should a policy pilot be judged?
What should a pilot evaluation measure?
It should measure outcomes tied to the policy’s stated aim, alongside practical details such as reach, delivery and participant experience. It should also explain what the measures cannot establish, especially when the trial was not designed to identify cause.
Does a small sample make a pilot useless?
No. A limited trial can expose confusing rules, delivery burdens or barriers that would be costly to overlook later. Its findings should be presented at the level the design supports, rather than stretched into a broad claim.
When is it reasonable to expand a pilot?
Expansion may be reasonable when the policy goal is clear, delivery responsibilities are understood, and decision-makers have a plan to address unresolved questions as the program grows. A cautious expansion can test whether results hold in new settings instead of treating the first trial as a final verdict.
What if the pilot produced mixed results?
Separate results by outcome and implementation condition before calling the trial a success or failure. Mixed findings can show that one part of the design is promising while another needs revision, or that the policy reached some groups more effectively than others.
What should happen before a wider rollout?
When a pilot leaves important questions open, the next move need not be an immediate choice between stopping and expanding everywhere. Decision-makers can revise the design, extend learning in a different setting or proceed in stages while tracking whether the original assumptions still hold. Each option should name what uncertainty it is meant to resolve.
A useful decision record says what the pilot supports, what it does not support, and what evidence would change the next decision. It should also state who will monitor delivery and how problems will be acted on. That turns evaluation from a ceremonial verdict into a working part of policy design.
The pilot project myth fades when a trial is treated as a source of bounded evidence, not a miniature promise of future performance. When you encounter a confident claim that a pilot proves a policy works, ask which people, conditions and outcomes the trial actually covered. That question gives the evidence room to be useful without asking it to say more than it can.